Could you do an office job with HSK 3?
 Leon·September 13, 2026·6 min
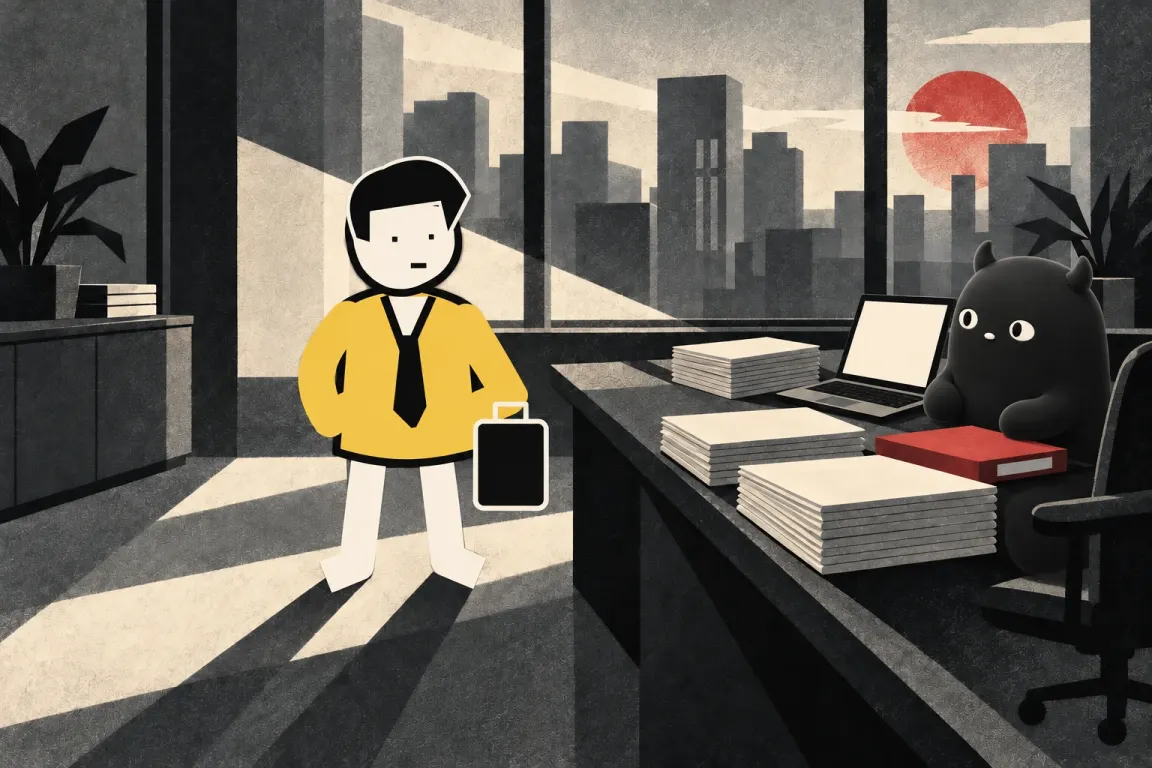
The HSK 3 list matched 60.4% of the words in our scripted office week.
We used AI to write the scenes, then counted their vocabulary. No learner or agent attempted the job, so that percentage cannot tell us how much an HSK 3 learner would understand.
For Dengdeng, our Chinese reading app, we built an illustrated version you can explore. Follow Chen from breakfast to the office, open the conversations, and tap the Chinese for pinyin and meaning.
The script has 100 selected mini-scenes across five weekdays. You can read it in full, including the messages, document excerpts, and counts for each scene.
The Chinese has not had an independent native-speaker review. Chen’s replies assume he knows the language and the job.
The working week
Chen is a junior project coordinator at a small Shanghai e-commerce services agency. He prepares the data for a client’s monthly operations report. His colleague writes the commentary; his manager checks it before it goes out.
On Monday, the draft is due Wednesday evening. On Tuesday, the client asks to see it before a Wednesday afternoon call. The final report is still due Friday.
Finance has not finished checking a refund. Two tables count different things. The client approves the images but leaves the price pending.
Those details continue through the week. Chen gets the missing figure, clarifies what belongs in each table, and checks which version has been approved. Friday’s review catches a chart with an old number.
There is also breakfast, lunch, a parcel at reception, and a file that will not open. A business taxi trip leads to an expense claim. Finance returns it because Chen attached the invoice and payment screenshot but left out the trip record.
The script shows time spent on spreadsheets and other work between conversations. We have not filled those intervals with invented dialogue or estimated word counts.
These are selected moments from one fictional job. The choice of role and situations affects every count below.
The HSK list
The older HSK 3 description includes basic communication at work. It does not promise that someone can independently handle client revisions or follow a fast meeting. That version has a 600-word vocabulary list. Official HSK 3 description.
We used the November 2025 exam syllabus, which has 1,000 numbered entries through Level 3. After removing word-sense numbers and duplicate spellings, there are 988 written forms to match. Official syllabus.
The older exam list and the 2021 proficiency standard contain different words. Our results apply to the named 2025 list.
The word count
The script contains 3,490 word occurrences and 809 distinct word forms. A word used ten times contributes ten occurrences and one distinct form.
That distinction matters when you read claims about how many words people use each day. The often-quoted estimate of roughly 16,000 from Mehl and colleagues counts spoken words, including repeats.
A 2025 follow-up pooled 2,197 participants across 22 samples and found large differences between individuals. Neither study gives us a daily vocabulary requirement for a Chinese office job. Tidwell et al., 2025.
The 809 forms here are what one tokenizer found in this script. A longer script or a different job would produce a different set.
| Selected script | Word occurrences | Exact HSK list matches |
|---|---|---|
| All scenes | 3,490 | 60.4% |
| Work-related scenes | 2,949 | 58.3% |
| Everyday scenes | 541 | 71.9% |
Work-related scenes include the business trip and work messages at home. Everyday scenes include food orders, personal travel, and conversations unrelated to the job.
The first, shorter version of the script matched 69.4%. After we expanded it and revised the work sequence, the match rate fell to 60.4%. We chose the situations and wrote the language; those choices affect the result.
Ten extra office terms
We kept every sentence the same and counted ten more recurring office terms as known. They include words for client, confirmation, data, files, attachments, and versions.
Across the script, exact coverage goes from 60.4% to 65.0%. In work-related scenes it goes from 58.3% to 63.6%. You can switch between the two assumptions in the interactive results and inspect all ten terms.
We chose the terms from this same script, using a specified set of office-word candidates. That shows how much these particular words affect the count. We have not tested them as a study plan or measured how long they would take to learn.
Understanding the instructions
Chinese does not mark word boundaries with spaces. The tokenizer sometimes groups familiar pieces into a form that is absent from the list. An exact match also tells us nothing about whether someone knows the meaning used in that sentence.
A more permissive check accepts forms made entirely of listed parts, plus one common shortened negative form. That gives 70.9% coverage on the same script. Familiar parts can still combine into an unfamiliar meaning.
Take the instruction to keep a pending refund in a separate item. You need to understand which refund, why it is separate, and where to put it. Recognising the surrounding words is only part of that task.
Chen asks the right questions because we wrote his replies. To answer the title’s question, we would need real learners to attempt reviewed workplace tasks, with clear success criteria and a record of any help they received.
For now, you can open the scenes and see which words you would need to look up.
Method and data
The count uses jieba 0.42.1 with its default dictionary and HMM disabled. We added no HSK entries to the tokenizer. We keep tokens containing Chinese characters and exclude punctuation, standalone Latin letters, and Arabic numerals. “Distinct forms” means distinct token strings; the boundaries have not been independently checked.
Both sides of conversations and selected written text are counted. English descriptions, timestamps, speaker labels, and notes about work between conversations are excluded. Repeated passages count each time they appear.
Download the script with per-scene counts and results with vocabulary frequencies. The results include a source-corpus hash, the tested list size, and the ten-term assumption. The lab’s method notes give further details.
For more Chinese reading practice, try today’s Dengdeng story previews. Tap unfamiliar words for pinyin and meaning.
Also on the Blog
Singles' Day in Chinese
11 November started as 光棍节, a student joke about being single, and became 双十一, China's biggest shopping festival. Here are the words for it: 预售, 定金 and 尾款, 满减, 凑单, 剁手, and a lot of 快递.
Nov 2, 2026 · 6 minRead 
Dengdeng v2 is here
Dengdeng v2 adds character chats, Beginner stories, cartoons, and a new Today screen. Available now on Android, with the iOS release to follow.
 Oct 19, 2026 · 3 minRead